I like the quote from Hilbert that was brought up in the article: "we must know, we will know".
With AI, it might be the case that we don't know, we won't know, but the machine does.
The central question, namely whether humans should be in the loop, will be repeated again and again in the years to come for all industries, starting with mathematics.
Don't conflate your self-worth with your ability to produce in the economy, or your test score, or which college you went to, or how good of a programmer you are. It's such a tragedy that we are so obsessed with achievement and competence.
Why should I be measured by how well I do things. In fact do we think human value can be measured at all?
The modern world has way too much content to commit to memory. Our brains would explode. Maybe 2500 years ago it was still possible to functioned as an adult without writing things down.
If we didn't have writing we wouldn't have to memorize that much stuff. The world would probably be worse for it. But that wouldn't have been obvious in Socrates' time.
It's like interest rates. I used to think it's weird why people are so obsessed with a couple percentage points. But it's turns out those couple of percent could mean hundreds of thousands of dollars difference for a 30 year mortgage
Completely agree! I find writing deeply memetic - in that I often catch myself imitating the flow, style, word choices, punctuation and grammar of whatever reading material I'm currently immersed in.
This unfortunately does not bode well for my writing ability as I read emails and Claude output all day. Recently, I've been reading a lot of building codes and compliance documents and I've develop annoying ticks like using "shall", "need not", "take no exception", overuse of passive voice, etc.
My hypothesis is engineers suck at writing by default unless they do extra-curricular reading. I read a lot! But sadly it's often textbooks, journal papers, documentations, and Claude. I'm envious of great writers, but I don't have time to read Keats. I'm immersed in Stewart, Strang, and whatever Claude is feeding me next.
T.R. Napper explicitly states that you do in his piece:
> But I am saying this: go look at your phone, and tell me what your average screen time is per day. Two hours? Five? Seven? If so – shut up: you’ve time to read.
It doesn't have to be Keats. Start by building the habit (read in bed before sleeping!) and just read whatever you enjoy. If Keats seems like a hurdle, just pick up Pratchett or Tolkien.
You can but at least personally I don't think I'd get much out of it if I did it that way. 30 seconds is only enough for me to topically skim the latest headlines.
Try it. Leave your phone at home. Carry a paperback book. Whenever you have time to kill and look for your phone, take out the book. See what happens. You may be surprised.
I find it really amusing that there's a sort of standardized Hacker News style that we all follow to some degree or another. It's very polite and academic.
This style is forced on us by the dislikes. I believe everyone including me walks on egg shells while writing on hacker news. Becausethe moment your words evoke a frown on someone's forehead then you are in danger of getting a barrage of dislikes. And on Hacker News some if not everyone are treating as if it's a LinkedIn where some magical collaborator or a VC would view all my posts and comments and lend me a hand and say. He you are filled with interesting ideas and expertise with the "karma" to match. Why not work with me on n my million dollar project. Atleast that's on my mind. I believe that's what many are thinking too. But since Hacker News is basically software and computer people so their writing style would look like academic too
Its a struggle trying to "imitate the style" in writing. In music, you could keep playing all the songs in the style of your favorite artist and possible develop a close stylistic proximity to what you're imitating but in writing do you just write prose with the same wordings? i get the keep reading to develop your style but feels like adapting a style you want to master and then make your own variant is way harder in writing.
"Style" is complicated to copy in both cases if you don't know what you're looking for.
In music, you have voicing sparsity, changes in voice count, preferred pitch ranges, tension/release cadences, embellishments, richness, playfulness, and a host of other characteristics. Rachmaninoff, for example (among other things), favours active, moving octaves quite deep in the base, extremely rich chords in the middle treble, simple (local) rythymic patterns, and expanding simple ideas like repeated arpeggios into large parts of a piece. He has more voices than other pieces typical of his time, though they tend to be combined somewhat simply when contrasted with counterpoint exercises and other techniques typically involving fewer voices.
In writing, you have sentence length, sentence complexity (they're different), typical volume used to express an idea, specific word choices, whether you tend to observe concrete or abstract ideas, the level of "truth" in your statements (in many flavours -- deadpan humour being quite different from a boldfaced lie directed toward the reader), technique choice used for signposting, willingness to violate "rules," and so on. If you picked even one project proposal from me at $WORK, you could reliably separate it from those written by hundreds of other engineers just by a few quirks -- habitually providing one level of motivation deeper than is typically expressed in technical writing (not just what we're doing, but what we're not doing and why we made that choice), a tendency to use British spellings and US words, a pattern of contracting any verb tense, sometimes with multiple apostrophes (e.g., "there'll've been"), refusing to terminate a non-exhaustive list without informing the reader that it's non-exhaustive, and so on. If you look at the reasons and motivations for one of those quirks, it's that I tend to have complete ideas (in technical domains) and want to express them completely and have found that every missing detail causes eventual problems -- only tempered by the fact that the requisite length tends also to cause important details to be overlooked on a casual read, which provides a mild damper on length. Understanding that motivation makes it easy to apply it as if you were me even when you don't have concrete examples regarding specific quirk/scenario interactions.
Very cool analogy with Rachmaninoff. The quirks are the differentiator and its important to recognize these deliberate choices you point out and it's not just a checklist. (Note to self to annotate more and deliberately study/reflect on those annotations to understand that construction/quirk)
I think the issue here might be that you're familiar with what "style" is supposed to be in music, so you know how imitating it would look (rather, sound) like.
On the contrary, you may have no idea what style means in the context of writing, so you can't fathom what imitating writing style looks like.
I honestly don't know precisely either, but a couple of things to mull over: Clarke and Asimov are said to have a "dry" style. Most of their novels are "story". On the contrary, Eco describes things in very minute detail (there's a whole chapter in "The name of the rose" that is the description of a door).
Those are examples of elements of style you may be able to reproduce and that aren't limited to wording.
Another reset tip I've implemented to great success is to drive in complete silence. No music, no podcast, no radio.
This way, I've turned my daily commute into a kind of meditation practice.
At first, you'll think about a million random things, and the 20 minute commute turns into a 40 minute commute mentally. Often you'll zone out and replay argument, write essays in your head. But if you try to relax and concentrate, after a while, you'll start to be more present and notice pedestrians, weird signs, potholes, restaurant you've never paid attention to, different types of overpasses, etc.
Another fun exercise: every once in a while, I flip a coin and if it lands head, I'll allow myself to listen to music, and the music becomes a treat again rather than random background noise! It's great and I've added so many more songs to my playlist because I actually notice them
> "The chatbot personas are deeply misaligned with you, and aligned with their owners; and the economic incentives are to farm you with ads and subscriptions, while racing not to amplify you but to replace you."
> "On my visits to the Bay Area, I would ask AI researchers or interns why they are doing their current research or projects, when in a year or three agentic LLMs could probably do them; they rarely had a good answer, or any idea what they would be doing in 3 years"
> "One programmer driving 10 Claude instances, because he has to review their work, will never be as valuable as fully autonomous Claudes where there can be almost arbitrarily many instances, like 10,000 instances… but such scaling requires removing him from the loop as much as possible. And this is true of everyone else, whether lawyers or writers or researchers: increasingly, you are the bottleneck to be optimized away."
I fully support the 3 core principles of GA: (1) Enhancement, not replacement (2) Mental Sovereignty (3) Self Actualization, which I think is a path to a more humane future.
Leaving AI completely aside, it still amazes me that people finds "novel" the idea of removing highly-paid white collar intellectual workers (software developers or otherwise) completely out of the loop.
No-code platforms date back to the 80's. Getting rid of engineers in general is even older [*].
Even relational databases and SQL were initially promoted as "ways to get rid of those expensive programmers to access your data" because they resembled some form of English.
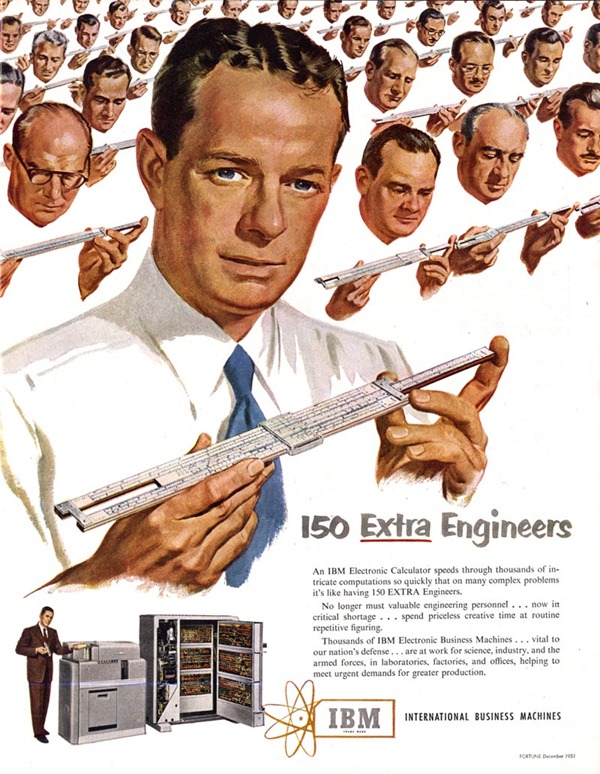
The funny thing about the ad below is that stuff like "stop hiring / get rid of humans" would have been seen as highly insensitive in 1950's America, so they touted that as "put them to do something more important".
It's novel because previous rounds of automation were about automating specific tasks or well-scoped functions. There was always an implicit understanding that the white-collar worker would be freed to spend their time on more valuable, higher-level problems. But this time is different because of the generality of the technology. Agents promise to automate the process of thinking itself. And in many domains they can learn new tasks as fast as white-collar workers can find them.
> It's novel because previous rounds of automation were about automating specific tasks or well-scoped functions. There was always an implicit understanding that the white-collar worker would be freed to spend their time on more valuable, higher-level problems. But this time is different because of the generality of the technology. Agents promise to automate the process of thinking itself. And in many domains they can learn new tasks as fast as white-collar workers can find them.
Nah, sometimes the expectation and advertisement was that you could let go of the white collar worker because you're paying the overseas person 1/10th the amount. And "overseas person" is pretty general.
"Everybody knew" it was a bad idea to get a CS degree for a bit after the dot-com bust because of that.
(Some white-collar industries did get hit much harder by that; VFX is one I've heard in that context quite a bit.)
That's a good point. However, overseas people are still people. They need to sleep, get sick, and the better they get at their jobs, the more money they will demand. The cheap ones also often have communication barriers and work slower than the workers they're replacing.
AI models get better and more efficient every 3 months, run around the clock, can be copied infinitely, and unprecedented amounts of capital and research talent are being thrown at any limitations we can see with them (such as problems writing correct code in 2024, lack of agency in 2025, autonomy and self-improvement in 2026). That's the difference between labor replacement through outsourcing vs. labor replacement through automation.
We are either living in different worlds, or squabbling over different meanings of words.
Models have absolutely acquired agency as of 2025. Developers are no longer copy-pasting code from ChatGPT into their text editor, they're working with agents like Claude Code and Codex that can edit code, run terminal commands, do web searches, manage their own context windows, sift through gigabytes of logs with datadog MCP, etc.
Self-improvement is also being worked on. Claude Tag learns over time in slack convos. My company also has an agent that updates its own skill files after every conversation so that we don't need to keep reminding it about the same workflows every time. Is it clunky as hell? Yes. Are the labs plowing billions of dollars into "continual learning" and "recursive self improvement"? Also yes.
What you call a model acquiring agency I call plain old software with productivity workflows designed by humans, with deliberate goals. We must separate “model” and an execution environment using a model. [Model] ≠ [A glorified shell script doing API calls in a control flow based on heuristics]. Agents are not AI, they are plain old software. The weights are the model, and that very much remains a static artifact (and pre-post training models haven’t improved much over the last few years).
What you call self improvement is a duck tape hack to imitate persistence and save on inference. Every time you do an API call, anything that needs to be processed is sent to the model. Narrowing that context down saves money. Finding clever ways to do that improves apparent performance and value. The cleverness is still human.
These are all useful innovations on top of LLMs, which remain models that generate text and symbols based on static weights, which in turn represent training data and the provider’s preferences.
You say that as if the culture difference with a truly alien intelligence is insignificant compared to the culture difference with an "overseas person".
(Even assuming "intelligent" is a sensible label to apply to an LLM holding hands with a shell script in an infinite loop)
I’m at a fully remote company with staff in at least 8 countries speaking at least 5 languages. It works out fine. A possible analogy to AI is that a lot depends on how you use it. The “skill issue” doesn’t disappear, at least not yet.
To colaborate a bit with the no-code part, I worked at a place where they had some flows made with n8n, but the last one from non tech/software engineering left the company and left a bunch of flows breaking, because of some edge cases the flows aren't handling like reissuing credentials, throtling or bad input. The people dependent of said flows reached out to the engineering team to help fix them!
I don't think the no-code comparison is valid, it's always been fundamentally flawed since its many leaky abstractions sitting on top of systems programming code
LLMs can't replace developers but its foundationally different because it can operate on systems code instead of building abstractions on top
Marketing about a more efficient product that requires fewer engineers is obviously not new. The idea that human engineers are obsolete is pretty new, that's the claim that is getting pushback.
I understand that but I think it's in direct proportion of the money being raised, spent and thrown around, including the price tag, to replace such engineers. The more money you ask for, the wilder the claim needs to be.
> > "On my visits to the Bay Area, I would ask AI researchers or interns why they are doing their current research or projects, when in a year or three agentic LLMs could probably do them; they rarely had a good answer, or any idea what they would be doing in 3 years"
I heard this already when ChatGpt came up. Still waiting to be fully obsolete.
I can find agreement with a lot of this post (and probably misunderstand just as much), but it's striking to me that it seems to overlook or avoid the obvious moral/ethical option: Pushing AI towards Personal Computing.
It seems clear to me that if these models are to have any benefit for humanity then they must be made directly available to as many humans as possible. Right now that cost and effort is astronomical, but general computing also went through a mainframe/shared model before becoming personalized.
I believe The Personal Computer was and still is a gift to humanity; for those with an interest in gathering its yield. And now we have an interface with it that can attempt to introspect its' program and speaks human tongue! Imagine what could have been done with this at the time...
But if that approach clutches too many pearls to stomach (and I agree it's not all roses) then I'd submit that anyone who champions less is seeking to become our master.
For 20 years my job has been automating my job away. I remain unafraid of my future necessity, and as always, excited for the work I get to do because of the work I no longer have to do.
The last 200 years of science, technology, and engineering is a long story about eliminating work people had to do being replaced by higher level work. Each time, each wave, there was always the FUD about the work nobody had to do any more and each time there were always new things to do enabled by people no longer having to do so many of the old things.
The human won't exit the loop. The people who imagine they will have, at the same time, too much and not enough imagination. Their endgame is always some kind of hand waving magic where suddenly everything is fixed and works.
Previous technologies eliminated single categories of worker at a time. The machine learning that people are working on these days threatens to replace very broad swaths of the workforce, of many countries, over a very short period of time.
My opinion is that juniors need time in the saddle to develop good engineering judgement and taste.
Outsourcing critical thinking is seductive and a slippery slope. LLM lures juniors into feeling productive, and molds them into ineffectual middle managers to be readily replaced when there's a bad quarter.
Yes exactly. The mids of my previous team where submitting PRs that at first glance looked good, well documented and with a very clean and professional English.
As you started pulling the threads it was, usually, a mess of subtle bugs and over abstraction. But to them it was great, as it was llm generated and they (the mid devs) had no better judgement.


With AI, it might be the case that we don't know, we won't know, but the machine does.
The central question, namely whether humans should be in the loop, will be repeated again and again in the years to come for all industries, starting with mathematics.
reply